DOTA is the pretrain zoo. FAIR1M is the fine-grained optical set — 37 classes under five coarse groups. oriented-det v0.3 loads it natively, converts to DOTA folders, tiles 1024/200, and finetunes the matching DOTA 1× Hub checkpoint. There is no FAIR1M Hub zoo.
A full 12-epoch Rotated Faster R-CNN finetune reached 36.70% mAP50 on official val tiles. That looks terrible next to DOTA ~74% Task 1. It is in band for FAIR1M Faster R-CNN (literature ~31–35%; Oriented R-CNN papers ~39–42%).
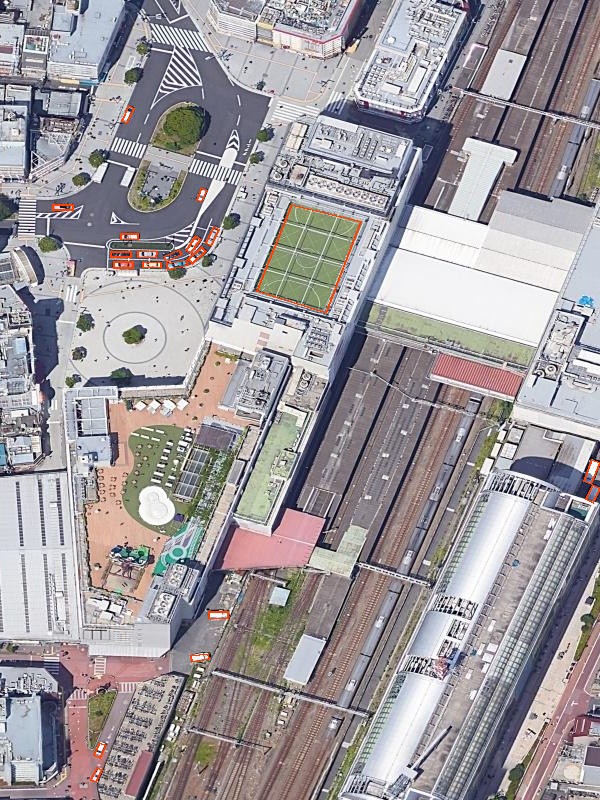
The dataset Link to heading
Sun et al., FAIR1M: A Benchmark Dataset for Fine-grained Object Recognition in High-Resolution Remote Sensing Imagery, ISPRS 2022. Official FAIR1M-1.0 has train 16,488 and val 8,287. Gaofen test labels are not public. Recipes train on train tiles only; val is not in training — unlike leaky DOTA eval-val.
| Source | Notes |
|---|---|
Kaggle ollypowell/fair1m-... | JPG + XML (~9 GB). CC BY-NC-SA 3.0 IGO. |
| Official Gaofen / ModelScope | TIFF + labelXml |
Images are typically 1k–10k px. Do not train whole-image like HRSC. Convert, then tile.
odet fair1m-to-dota \
  --data-root /path/to/data/FAIR1M \
  --output-dir /path/to/data/FAIR1M-dota \
  --splits train,val

odet tile-dota /path/to/data/FAIR1M-dota/train --tile-size 1024 --overlap 200 --min-overlap 0.7
odet tile-dota /path/to/data/FAIR1M-dota/val   --tile-size 1024 --overlap 200 --min-overlap 0.7

odet train --config configs/rotated_faster_rcnn/fair1m_le90_1x.json
The 37-way classifier is randomly initialized (class-count tensors skipped on load). Notebook: notebooks/kaggle_fair1m_tutorial.ipynb — a 1-epoch smoke. It will not reproduce 36.7%.
Local 1× Faster R-CNN: 36.70% Link to heading
From hf://rotated_faster_rcnn_dota_le90_1x, NVIDIA L4, ~24.5 h (runs/rotated_faster_rcnn/20260910-072116). Score ≥ 0.05, rotated IoU 0.50, non-empty val tiles.
| Epoch | Train loss | Val mAP50 |
|---|---|---|
| 4 | 0.496 | 30.03% |
| 8 | 0.456 | 33.71% |
| 12 | 0.412 | 36.70% |
Not the Gaofen hidden test. Not FAIR1M mAP_F. No Hub slug.
The bottleneck is class ID, not boxes Link to heading
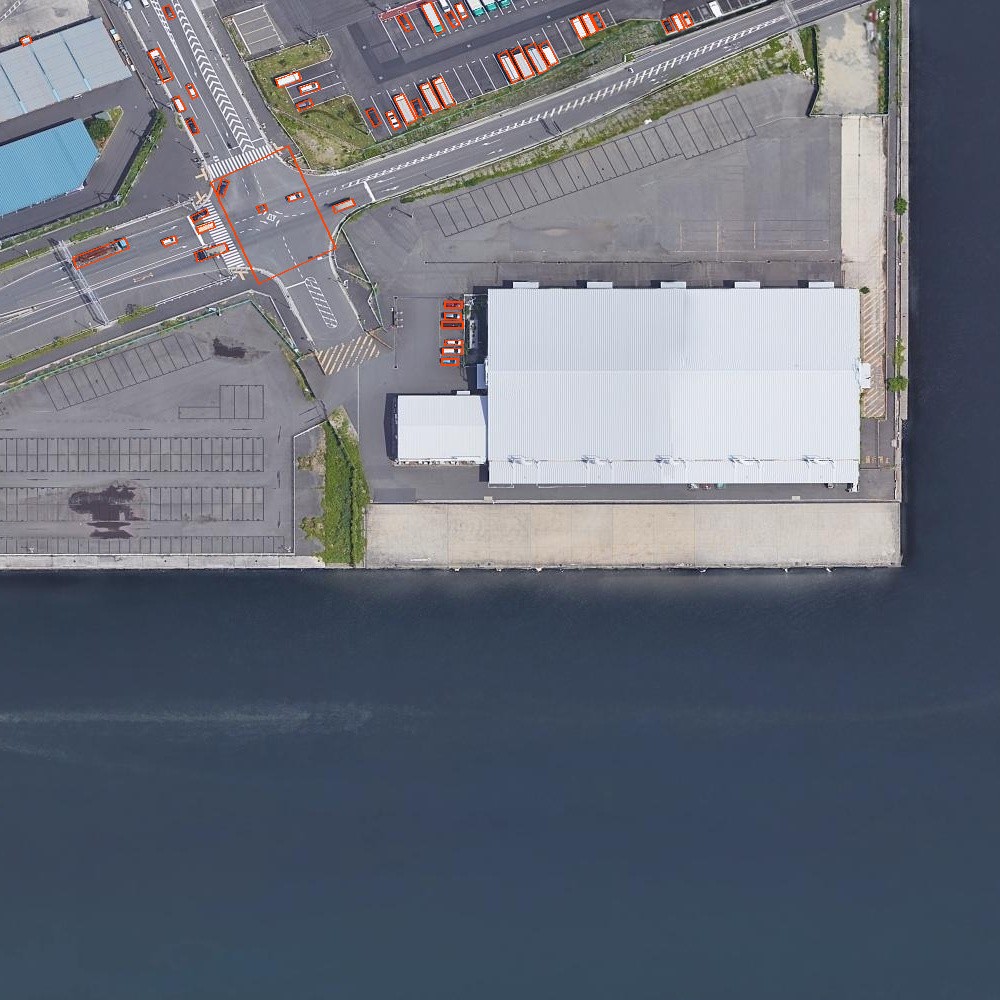
Epoch 12 mean best IoU vs any detection was 0.62, same-class 0.50, GT cover 62% (DOTA ~88%). About 32.6k ground truths had IoU ≥ 0.5 with a wrong-class box. Train imbalance is 1038× (Small Car 143,249 vs C919 138). Rare subtypes stay near 0 AP. Sports fields are easy (Baseball Field 88.5%, Tennis Court 81% on this run).
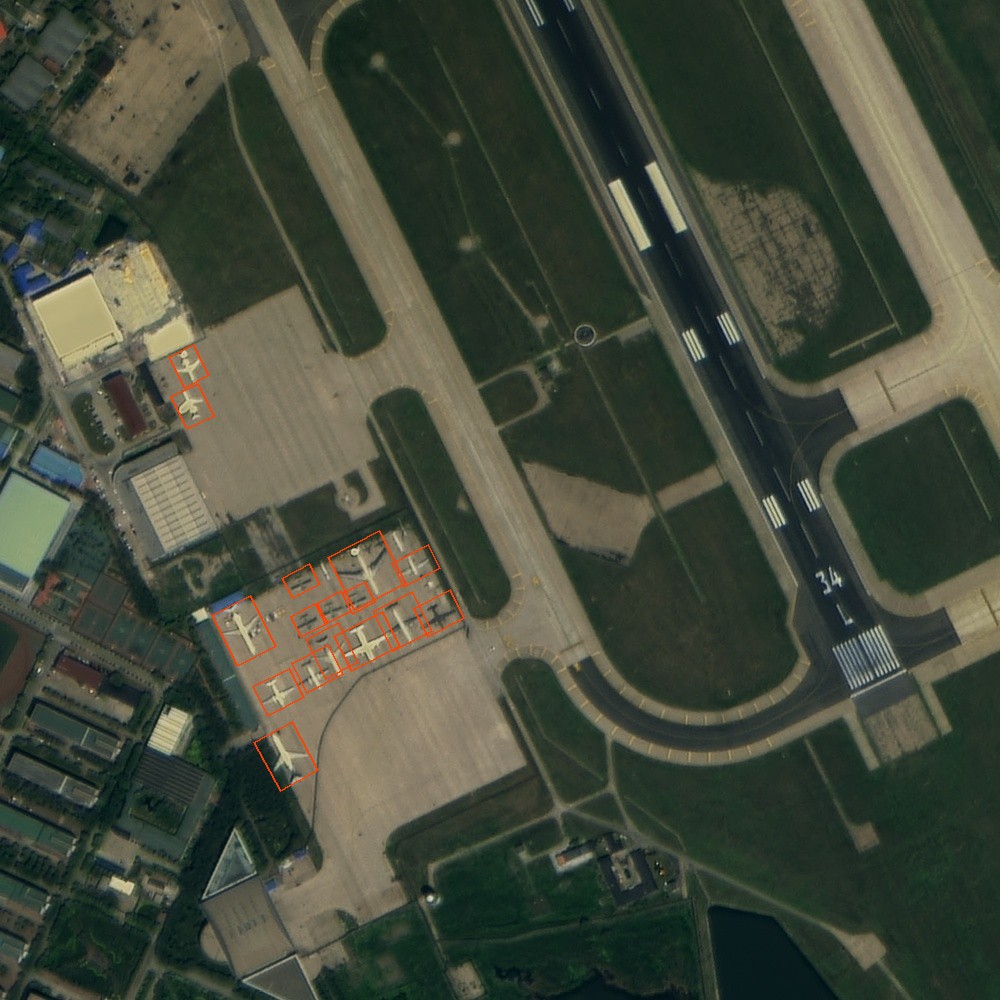
Literature band (different test sets; cited as a band only): FAIR1M paper Faster R-CNN R101 31.53%; later Rotated Faster R-CNN R50 ~33–35%; Oriented R-CNN R50 ~39–42%.
The 1× recipe uses unweighted cross-entropy. Loss and mAP were still moving at epoch 12 (train loss 0.412, mAP50 36.70%), and the 37-way head started from random weights. These are the levers that target that, not a different dataset. None of them has a published FAIR1M number in this series.
Resume, or a 3× schedule, from this checkpoint. Twelve epochs is the 1× budget. A 3× run is the longer MMRotate-style schedule (36 epochs) starting from these weights, so the head is not re-initialized. The curve had not flattened. More epochs are the cheapest bet if the only problem is that training stopped early.
Oriented R-CNN 1× (configs/oriented_rcnn/fair1m_le90_1x.json). Same tiles, oriented proposals instead of a horizontal RPN. Literature for Oriented R-CNN R50 sits about 39–42%, against about 33–35% for Rotated Faster R-CNN. That gap is mostly better RoIs, not a smarter subtype head. It will not by itself name a C919, but it is why the upper end of the band is higher than 36.70%.
Coarse-to-fine groups (loss.roi_grouped_ce_*). FAIR1M’s five groups are ship, vehicle, airplane, court, and road (FAIR1M_GROUPS). Early epochs can train those coarse labels while the head stays 37-way: a Boeing737 called a C919 is not an error while both are “airplane.” A step or linear_ramp schedule then hands the loss back to the fine names. This needs loss_type cross_entropy or class_weighted.
Class weights, or focal loss, for the 1038× imbalance. Inverse-frequency weights (class_weighted, or class_weight_*) stop Small Car (143,249) from owning the gradient over C919 (138). Focal loss (loss_type: focal) does the same job a different way: easy, frequent boxes contribute less, so rare subtypes are not washed out. focal_weighted applies the class weights on top of focal. Focal does not combine with grouped CE — the trainer ignores roi_grouped_ce_* when the loss is focal. Pick a curriculum (groups, then fine labels) or a reweighting (class weights and/or focal), not both at once.
Do not compare 36.70% to DOTA Hub tables.
Why no Hub weights Link to heading
The usual Kaggle dump is CC BY-NC-SA. The official test is closed. oriented-det supports FAIR1M for local train/metrics only. If your programme needs aircraft or vehicle subtypes, pretrain on a public oriented zoo, re-init the head, watch imbalance — on your licensed imagery.
Links Link to heading
- oriented-det docs — FAIR1M · v0.3 release note
- FAIR1M paper (arXiv)
- Previous: Oriented-Det v0.3.1 · HRSC2016
- Next: SSDD (28 Sep)